Every finding in InsightDueDiligence cites a page. That is only possible because the data room is read into page-level pieces before any agent looks at it: a policy block becomes fields, a loss run becomes rows, a legal letter becomes findings with a severity. In production the reading is done by InsightXtract; on a laptop and in the demo book, a stand-in reader with the same contract.
From file to cited pieces
Excel, CSV, text, image"] --> CK["Checks: allowed type,
signature, size limit"] CK --> OS["Object store
(never local disk)"] OS --> X{"Reader"} X -- "production" --> XT["InsightXtract:
OCR, layout, tables"] X -- "laptop / demo" --> ST["Stand-in reader
(same output shape)"] XT --> PC["Page-level pieces:
fields, rows, findings,
each with its page"] ST --> PC PC --> PB["Playbook checks
and the engines"] style PC fill:#e6efff,stroke:#2563eb style OS fill:#e7f8f1,stroke:#10b981
Uploads are refused unless they are an allowed type whose first bytes match (a “.pdf” that is not a PDF is refused), under the size limit, and going to object storage. Without object storage configured, uploads are refused outright rather than written to the server’s disk.
What gets read from each document type
| Document | Read into |
|---|---|
| Schedule of insurance | One policy per block: line, carrier, policy number, named insured, period, limit, retention, premium, trigger, program structure, retro date, collateral, financing, change-of-control clause. |
| Policy declarations | The same fields for that policy, plus the conditions text the tail agent quotes. |
| Loss runs | One row per claim: line, claim number, loss date, open or closed, paid, reserve, what happened. |
| Legal letters, Phase I, recall summaries | Findings with a severity, an area and any amount they quantify. |
| Contracts | Sections by number, so a liability cap is cited “§8.1, p.1”. |
One contract, two readers
returns the same shape from the document text
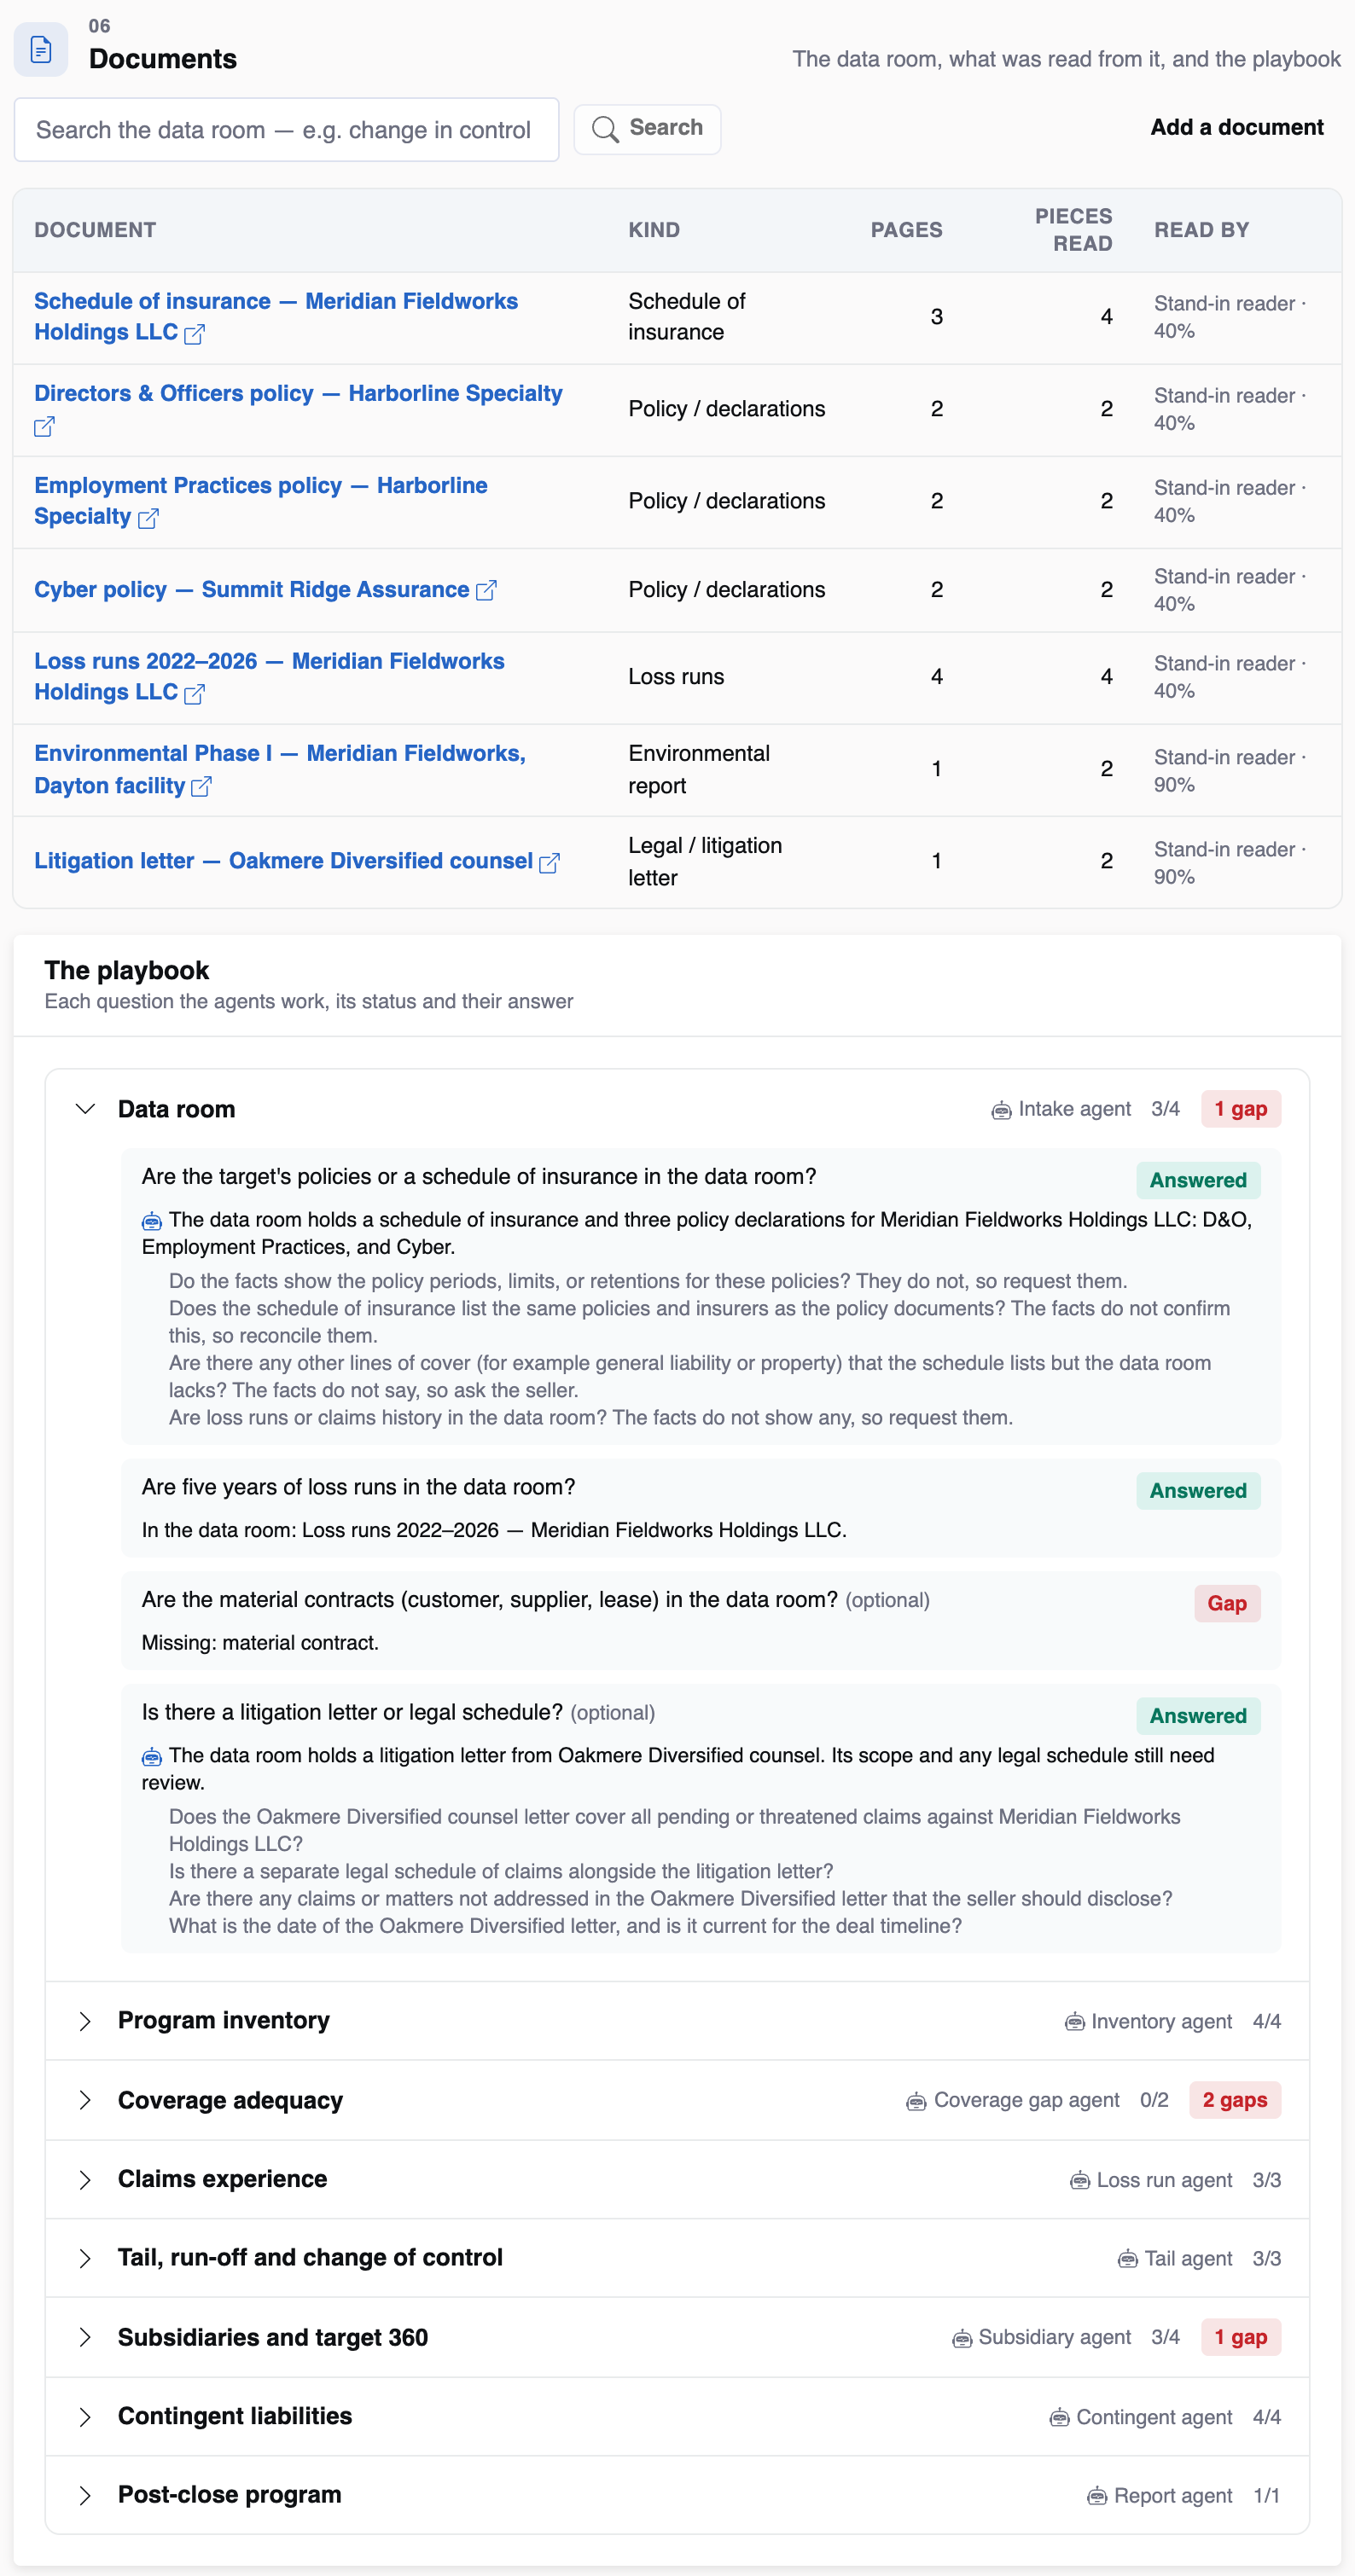
The Documents zone shows, for each document, its kind, pages, how many pieces were read and by which engine with what confidence. On the demo book the engine column says “Stand-in reader”, because that is what read the synthetic documents. Nothing on the screen pretends otherwise.
Search over the data room
The same pieces power the data room search (“change in control”) and the copilot’s search tool, so an answer about a clause points at the same page a reviewer would open.
Why page-level matters
A finding that cites “the D&O policy” sends a reviewer looking. A finding that cites “Directors & Officers policy — Harborline Specialty, p.1” (an illustrative carrier) lets them approve it in seconds. Across thirty findings, that is the difference between a review and a re-do.
Questions we get asked
Can it read scanned loss runs?
In production InsightXtract handles OCR, layout and tables. The quality of the read is shown as a confidence per document, and a low one is visible to the reviewer.
Are privileged documents handled differently?
Documents can be marked privileged, and data room search leaves privileged documents out unless they are asked for explicitly.

